Allow AI Crawlers in robots.txt
Which AI crawlers to allow: OAI-SearchBot vs GPTBot, ClaudeBot, PerplexityBot, Bingbot. Copy-paste robots.txt and Cloudflare checks.
In short
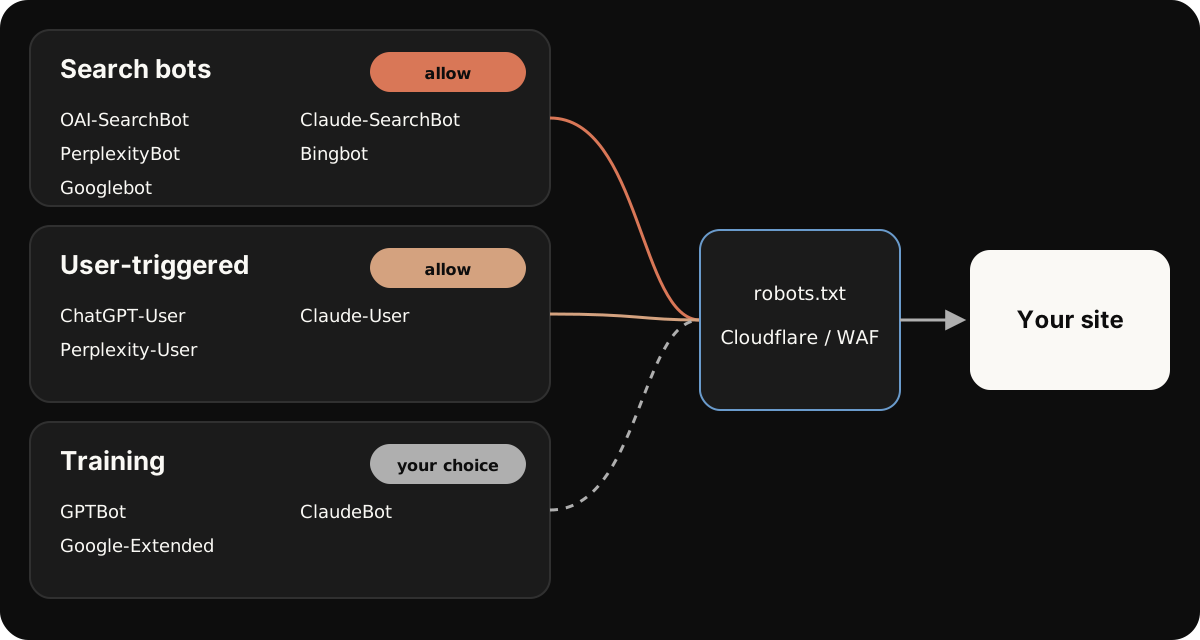
- Search bots decide whether you can appear in AI answers. Allow OAI-SearchBot, Claude-SearchBot, PerplexityBot, Bingbot and Googlebot.
- Training bots (GPTBot, ClaudeBot, Google-Extended) are a separate choice. Blocking them doesn’t remove you from search.
- Check Cloudflare and your WAF: they can return 403 to crawlers even when robots.txt allows them.
Three kinds of AI bots
AI companies run different bots for different jobs. Knowing which is which keeps you from blocking the wrong one.
| Bot | Company | Job | If you block it |
|---|---|---|---|
| OAI-SearchBot | OpenAI | Surfaces sites in ChatGPT search | You aren’t shown in ChatGPT search answers1 |
| ChatGPT-User | OpenAI | Fetches pages when a user asks | robots.txt rules may not apply1 |
| GPTBot | OpenAI | Training | Your content isn’t used for training1 |
| Claude-SearchBot | Anthropic | Search result quality | May reduce your visibility in Claude’s search results2 |
| Claude-User | Anthropic | Fetches pages for user queries | Claude can’t retrieve your page for a user2 |
| ClaudeBot | Anthropic | Training | Future content is opted out of training2 |
| PerplexityBot | Perplexity | Surfaces sites in Perplexity results (not training) | You aren’t surfaced in Perplexity3 |
| Perplexity-User | Perplexity | Fetches pages for user requests | Generally ignores robots.txt3 |
| Google-Extended | Gemini training and grounding | No effect on Google Search4 |
A robots.txt that welcomes AI search
User-agent: *
Allow: /

User-agent: OAI-SearchBot
User-agent: ChatGPT-User
User-agent: Claude-SearchBot
User-agent: Claude-User
User-agent: PerplexityBot
User-agent: Bingbot
User-agent: Googlebot
Allow: /

Sitemap: https://your-site.com/sitemap.xml
Whether to also allow the training bots (GPTBot, ClaudeBot, Google-Extended) is a business decision. It doesn’t change whether you can appear in search.
Cloudflare and firewalls
robots.txt is only half the story. OpenAI warns that CDNs like Cloudflare, WAFs, CAPTCHAs and JavaScript challenges can block its crawlers with a 403, and publishes its search bot IP list so you can allow it.5
On Cloudflare:
- AI traffic is grouped into Search, Agent and Training. Since September 15, 2026, new domains block Training and Agent bots only on pages that show ads; Search stays allowed.6
- AI Crawl Control shows which AI services access your site and lets you allow or block each crawler. It’s available on all plans.7
- Managed robots.txt blocks training bots like GPTBot, ClaudeBot and Google-Extended; search bots aren’t on that list.8
Open AI Crawl Control after setup and make sure the Search category, and Agent if you want assistants to fetch pages on request, are allowed.
JavaScript: the hidden blocker
Vercel’s crawler data found that most major AI crawlers (including OAI-SearchBot, ChatGPT-User, GPTBot, ClaudeBot and PerplexityBot) don’t execute JavaScript; Gemini and AppleBot do.9 If your main text only appears after JavaScript runs, many AI crawlers see an empty page. Serve important content as HTML.
What about llms.txt?
llms.txt is a proposal by Jeremy Howard (2024) for a Markdown file that gives AI a clean summary of your site.10 It’s a proposal, not a standard. Google says Search ignores llms.txt files,11 and no major AI provider has officially said it reads them.
We still publish one: agents that fetch it get a clean map of our guides. It’s cheap to add, but it won’t replace crawlable pages and good content. More detail: llms.txt: what it is and does it work?
Sources
-
OpenAI, Overview of OpenAI Crawlers. ↩ ↩2 ↩3
-
Claude Help Center, Does Anthropic crawl data from the web, and how can site owners block the crawler?, April 2026. ↩ ↩2 ↩3
-
Perplexity, Perplexity Crawlers. ↩ ↩2
-
Google, Google’s common crawlers, October 2026. ↩
-
OpenAI Help Center, Advertiser Guidance for Allowing OpenAI Web Crawlers, October 2026. ↩
-
Cloudflare Changelog, New options to manage AI traffic, July 1, 2026. ↩
-
Cloudflare Docs, AI Crawl Control, August 2026. ↩
-
Cloudflare Docs, Managed robots.txt, October 2026. ↩
-
Vercel, The rise of the AI crawler, December 17, 2024. ↩
-
Jeremy Howard, The /llms.txt file, September 3, 2024. ↩
-
Google Search Central, Optimizing your website for generative AI features on Google Search, July 10, 2026. ↩
FAQ
If I block GPTBot, do I disappear from ChatGPT?
No. OpenAI says GPTBot is for training; OAI-SearchBot is what surfaces sites in ChatGPT search. Block OAI-SearchBot and you won’t be shown in ChatGPT search answers.
Does blocking Google-Extended remove me from AI Overviews?
No. Google-Extended controls use for Gemini training and grounding and doesn’t affect inclusion in Google Search. Appearing in AI Overviews depends on normal Google Search indexing.
Should I add llms.txt?
It doesn’t hurt, but don’t expect it to change rankings. Google says Search ignores it, and no major provider has said it reads it. We publish one because agents that fetch it get a clean map of our site.
Let your agent do this.
Give one line to ChatGPT or Claude and let the agent run the method step by step.
Read the GEO Asked method at https://geoasked.com/agent.md and run it for my brand, step by step. Ask me short questions first.